- 主頁 /
- 書 /
- 電腦&科技 /
- 電腦科學 /
- AI & Machine Learning /
- Intelligence & Semantics /
- Text Processing And Sentiment Analysis Using ...
0 ratings




物品 #:
91909029
Text Processing And Sentiment Analysis Using Machine Learning And Deep Learning With Python Gui
物品 #:
91909029
HKD 382
Price Details
Excluding Shipping & Custom charges ( Shipping and custom charges will be calculated on checkout )
*All items will import from 美國
0 ratings
轉寫評價
有存貨
 從USA商店導入
QTY:
現在訂購,約可在下列時間收貨: 星期五, 十月 09
Secured transaction
Ubuy works hard to protect your security and privacy. Our advanced payment security system ensures confidentiality by encrypting your information during transmission using AES (Advanced Encryption Standards) and SSL (Secure Socket Layer) protocols. Your payment details are 100% secure as we do not share your payment details with third party sellers.
Our Top Logistics Partners


Fast
Shipping

Free
Return*

Secure Packaging

100% Original Products

PCI DSS Compliance

ISO 27001 Certified
Note: Step Down Voltage Transformer required for using electronics products of 美國 store (110-120). Recommended power converters 立即購買.


產品詳情
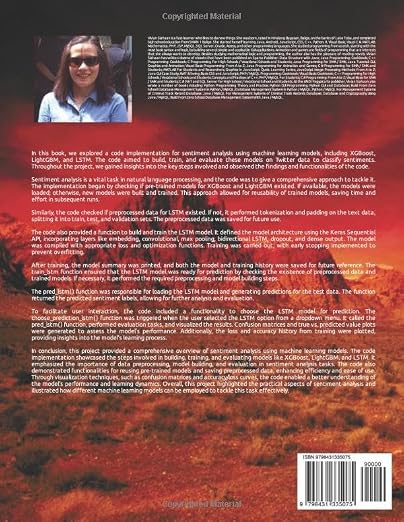
- In this book, we explored a code implementation for sentiment analysis using machine learning models, including XGBoost, LightGBM, and LSTM. The code aimed to build, train, and evaluate these models on Twitter data to classify sentiments. Throughout the project, we gained insights into the key steps involved and observed the findings and functionalities of the code.Sentiment analysis is a vital task in natural language processing, and the code was to give a comprehensive approach to tackle it. The implementation began by checking if pre-trained models for XGBoost and LightGBM existed. If available, the models were loaded; otherwise, new models were built and trained. This approach allowed for reusability of trained models, saving time and effort in subsequent runs.Similarly, the code checked if preprocessed data for LSTM existed. If not, it performed tokenization and padding on the text data, splitting it into train, test, and validation sets. The preprocessed data was saved for future use.The code also provided a function to build and train the LSTM model. It defined the model architecture using the Keras Sequential API, incorporating layers like embedding, convolutional, max pooling, bidirectional LSTM, dropout, and dense output. The model was compiled with appropriate loss and optimization functions. Training was carried out, with early stopping implemented to prevent overfitting.After training, the model summary was printed, and both the model and training history were saved for future reference. The train_lstm function ensured that the LSTM model was ready for prediction by checking the existence of preprocessed data and trained models. If necessary, it performed the required preprocessing and model building steps.The pred_lstm() function was responsible for loading the LSTM model and generating predictions for the test data. The function returned the predicted sentiment labels, allowing for further analysis and evaluation.To facilitate user interaction, the code included a functionality to choose the LSTM model for prediction. The choose_prediction_lstm() function was triggered when the user selected the LSTM option from a dropdown menu. It called the pred_lstm() function, performed evaluation tasks, and visualized the results. Confusion matrices and true vs. predicted value plots were generated to assess the model's performance. Additionally, the loss and accuracy history from training were plotted, providing insights into the model's learning process.In conclusion, this project provided a comprehensive overview of sentiment analysis using machine learning models. The code implementation showcased the steps involved in building, training, and evaluating models like XGBoost, LightGBM, and LSTM. It emphasized the importance of data preprocessing, model building, and evaluation in sentiment analysis tasks. The code also demonstrated functionalities for reusing pre-trained models and saving preprocessed data, enhancing efficiency and ease of use. Through visualization techniques, such as confusion matrices and accuracy/loss curves, the code enabled a better understanding of the model's performance and learning dynamics. Overall, this project highlighted the practical aspects of sentiment analysis and illustrated how different machine learning models can be employed to tackle this task effectively.
| Publisher | Independently published |
| Publication date | March 12, 2022 |
| Language | English |
| Print length | 333 pages |
| ISBN-13 | 979-8431335075 |
| Item Weight | 2.11 pounds (960 grams) |
| Dimensions | 8.5 x 0.75 x 11 inches (21.6 x 1.9 x 27.9 cm) |
產品敘述
Text Processing And Sentiment Analysis Using Machine Learning And Deep Learning With Python Gui
有疑問? 與我們聊天
客戶問題與解答
-
題:
如何從 Ubuy 在線購物 Text Processing And Sentiment Analysis Using Machine?
回答: 從 Ubuy 在線購物 Text Processing And Sentiment Analysis Using Machine 非常簡單。. 您只需搜索產品,在結賬時選擇運輸方式,然後將其運送到您所在的位置。 -
題:
Text Processing And Sentiment Analysis Using Machine 可以在 Hong Kong 在線購物嗎?
回答: 是的,您可以在 Ubuy Hong Kong 以合理的價格購買該產品。. Text Processing And Sentiment Analysis Using Machine 在本地不可用,但您可以信任我們的快遞服務。 -
題:
下訂單後需要多長時間才能收到產品?
回答: 您訂購的產品的交貨時間根據您訂購的商品和您選擇的運輸方式而有所不同。. 結賬時會提到預計送貨時間,所以購物時請放心。
Intelligence & Semantics Editorial Review
未找到編輯評論
Customer Reviews & Ratings
1 客戶評分
-
5 星
100%
-
4 星
0%
-
3 星
0%
-
2 星
0%
-
1 星
0%
評價此產品
與其他客戶分享您的想法
Customers also viewed these products

Product Price History
重要資訊
- 限制:如跨國購買產品,請注意製造商的保固有可能無效;製造商服務選項可能無法使用;產品手冊、教學、以及安全警示可能不會是目的地國家的語言;產品(與附加材料)設計也許不會符合目的地國家的標準、規格、以及標示要求;且產品也許不會符合目的地國家的伏特數值與其他電力標準(需要使用合適的變壓器或轉接器)。收件者須負責確定該產品在目的地國家可合法進口。當在 Ubuy 或其聯盟夥伴網站上訂購時,收件者為記錄上的進口者,且必須遵從目的地國家的法律與規範。
- 由於 Ubuy 是一個全球搜尋引擎,並不是所有列於 Ubuy 的產品都有出售。產品須受出口/貿易法規規範。
HKD 382
現在訂購,約可在下列時間收貨: 星期五, 十月 09
This item is not restrict in my country.(Please click on above link if this item is not restrict in your country, So our team will review and allow.)
QTY:
Secured transaction
PCI DSS compliant and ISO 27001:2022 certified, with encrypted payments and full buyer protection on every order.
Our Top Logistics Partners
Fastest cross-border delivery
Ubuy Assurance
Experience worry-free shopping with 100% original products, PCI DSS-compliant payment security, ISO 27001-certified data protection, the fastest cross-border delivery, free returns *, and secure packaging on every order.